A system can solve a difficult problem and still make a poor choice about which problem to attempt next. That distinction matters whenever we ask AI to investigate, discover or develop a narrative world without specifying every intermediate goal.
Research by Gaia Molinaro and colleagues provides a useful starting point. Their study finds substantial differences between human and language-model goal selection in a controlled learning task. It also invites a broader architectural question: who decides which part of the possibility space gets explored?
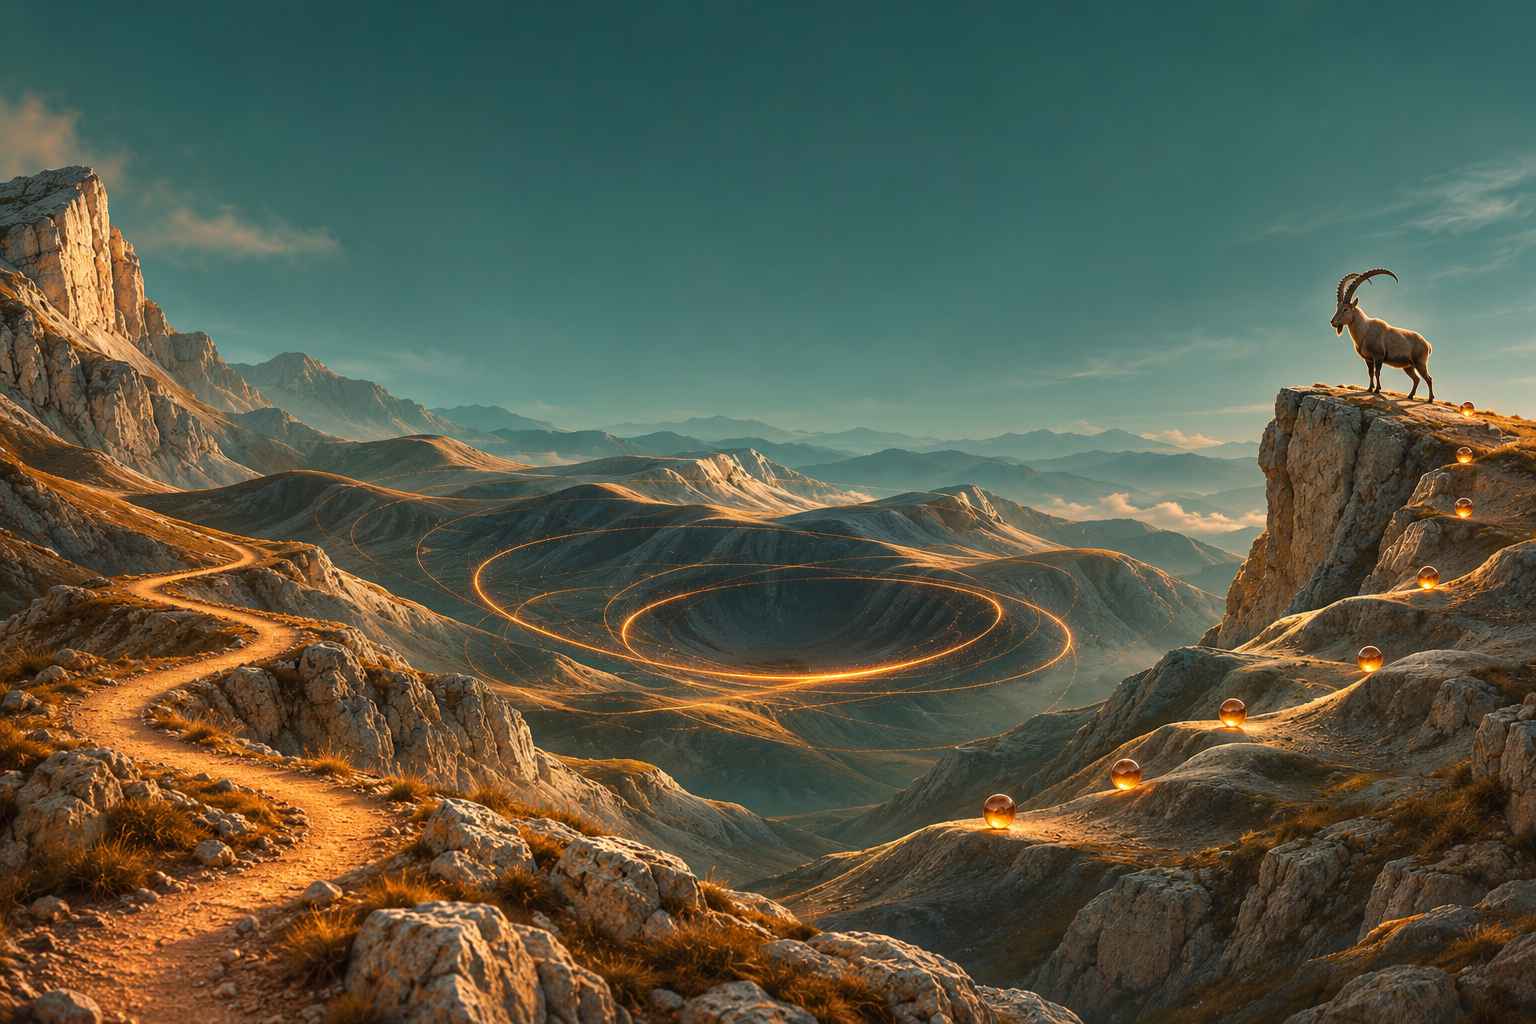
Three images help frame that question: a walker moving through neighboring states, a system circling familiar territory, and an ibex jumping onto a distant ledge. These are conceptual extensions developed here, rather than categories established by the researchers.
What the Goal-Selection Study Shows
In Language Model Goal Selection Differs from Humans’ in a Self-Directed Learning Task , Molinaro, Dave August, Danielle Perszyk and Anne G. E. Collins compare people with five models: GPT-5, Gemini 2.5 Pro, Claude Sonnet 4.5, Qwen3 32B and Centaur.
The abstract reports that people gradually explore and learn, with goals differing across individuals. Most tested models repeatedly use one discovered solution or perform poorly. Behavior differs between models but varies little between instances of the same model. Chain-of-thought reasoning and persona steering offer limited improvements. The authors caution that confirmation in applied settings remains necessary.
The distinction is between performing a specified task and selecting goals independently. The study challenges treating these models as substitutes for human goal selection in this setting; it does not establish a universal account of human or machine exploration.
Research scope: this article’s empirical summary is based on the abstract of version 3, revised October 16, 2026. The framework and architecture below are proposals, not additional findings from the paper.
Three Ways Through a State Space
A state space is the set of configurations relevant to a problem. In a narrative world, a state might specify who knows a secret, which alliances exist and what resources remain. A transition changes some part of that configuration.
Wandering: Local Exploration
A walker investigates nearby possibilities, observes what changes and chooses another step. This supports incremental learning and correction. Each transition can improve the working model of the environment.
The cost is distance. Reaching a substantially different configuration may require many intermediate steps. In a story, repeatedly asking what happens next can explore one branch deeply while leaving distant alternatives untouched.
Circling: Staying Near a Familiar Attractor
An attractor is a useful metaphor for a region that search repeatedly returns to. A system may produce different answers while preserving the same underlying solution pattern: another reconciliation, another betrayal, another variation on the successful plan.
The distinction is between surface variation and movement into a different region of possibilities. Ten differently worded outcomes can still share one causal structure.
Calling this attractor binding is an interpretation. The reported goal convergence does not establish a dynamical attractor, its mechanism or its boundaries. Demonstrating those would require an explicit state representation and measurements of trajectories through it.
Jumping: Non-local Exploration
A jump selects a substantially different candidate state and investigates what follows from there. Instead of generating every event leading to a broken alliance, the system temporarily assumes that the alliance has already broken and examines the consequences.
That assumption must remain visible. A proposed state is neither an observed event nor an accepted addition to canon. Its value depends on what it helps test, including whether a credible route to it exists.
Jumping can uncover overlooked possibilities. It can also spend resources on unreachable or irrelevant configurations. Distance alone measures neither insight nor quality.
The Ibex Principle
Imagine a mountain whose complete geometry is unknown. A walker climbs step by step. Another explorer repeatedly returns to familiar slopes. The ibex leaps onto a separate ledge.
In the thought experiment, the ibex then releases small marbles and watches them roll. Their paths reveal something about the local slope without requiring a complete reconstruction of the mountain.
The proposed method is simple: accept an incomplete world model, choose an interesting state, observe its dynamics and try to disprove your assumptions.
The marbles represent probes. Which dependency fails? Which expected outcome does not occur? Which constraint rules out the candidate state? A useful leap creates an opportunity to learn something specific.
This is a metaphor for search design, not a claim about ibex cognition or an experimentally demonstrated human learning mechanism.
A Hybrid Architecture for Exploration
For hybrid AI, this suggests separating the choice of exploration states from the model that describes and interprets them. A proposed architecture has four responsibilities:
- State representation: record relevant entities, relationships, constraints and uncertainties.
- Non-local exploration: select distant or underexplored candidate states using an explicit policy.
- Transition observation: run permitted transitions or bounded simulations and record their consequences.
- Falsification: check which predictions, hypotheses or constraints fail.
An LLM could generate hypotheses and explain results while another component controls state selection. A graph could preserve relationships and provenance, extending the blog’s discussion of graphs and agent decision spaces .
This separation creates an inspectable design choice: why was this state selected, and what did its examination establish? It does not guarantee better exploration. A selector can reproduce its own narrow preferences.
Observation also needs care. If the same model invents a scenario and judges its consequences, agreement can reflect shared assumptions. A simulator’s result tests behavior within that simulator; claims about the outside world require independent evidence.
Turning the Metaphor into Experiments
Four hypotheses could make the proposal testable:
| Hypothesis | Possible measurement |
|---|---|
| Certain model configurations revisit narrower regions than people | Distinct state regions visited under comparable starting conditions and budgets |
| Targeted jumps extend exploration | Coverage of distant regions compared with a local-search baseline |
| Non-local probes expose more failed assumptions | Independently checked prediction failures per unit of computation |
| Separate exploration control reduces repeated convergence | Revisitation rates across runs, alongside task quality |
These tests require a declared distance measure, a definition of a region and a shared accounting of resources. Token counts, environment interactions and human time are different costs; comparisons must say which they control.
Goal diversity, state-space coverage, information gained and solution quality should remain separate measures. A system that visits many irrelevant states should not outperform a focused investigator merely because it travels farther.
Why Narrative Intelligence Needs This Distinction
Narrative worlds combine fixed canon with unresolved possibilities. They rarely provide complete external ground truth, but established events and relationships still constrain what can follow.
Consider a city whose ruler depends on a guild for food distribution. Local exploration follows the next negotiation. Circling produces several versions of the guild demanding concessions. A non-local probe asks: what if the distribution network has already become decentralized?
That candidate state opens concrete questions. Who coordinates deliveries? Which groups lose influence? Does decentralization contradict an established resource shortage? What earlier changes would make it reachable?
The point is to inspect dependencies before writing an entire alternative storyline. As in Anti-Narratives Emerge from the Same World , different developments remain connected to a shared underlying state.
A contradiction can reject a branch under current canon, or expose an assumption that needs review. Either result is useful when the system preserves the reason. It becomes less useful when fluent prose conceals the missing dependency.
Navigation with an Incomplete Map
The study supplies a bounded warning about substituting model goal selection for human choice. The broader research opportunity is to design systems that choose unfamiliar states deliberately and evaluate what those states reveal.
Sometimes the right move will be another local step. Sometimes it will be a jump followed by careful probing. The architecture should make both choices possible and their costs visible.
An intelligent explorer needs ways to find useful starting points, examine consequences and discard assumptions—even while its map remains incomplete.
Or, less academically: be the ibex. Find a ledge worth testing.